

1. Observe the recorded behavior
Verify the prepared returns evidence and select a bounded worklist for human review.
Observe → Judge → Define → Replay → Compare
The first task is factual: confirm what the example preserved and inspect the population before deciding what was right or wrong. By the end of this page, you will have descriptive measurements and a bounded, varied worklist for human review.
Confirm the prepared evidence
The PydanticAI returns agent setup registered the logical agent returns-resolver and assigned its first immutable run specification the reference returns-resolver@1. That version stores the command, working directory, timeout, and declared tools Kitaru can use for later replay. Registration did not run the agent.
The setup also imported traces/langfuse-traces.jsonl under that exact version. One complete recorded run became a session; model calls, tool calls, tool results, and other events inside it became session nodes. Importing preserved the evidence and its source identity without calling the historical agent.
Do not repeat registration or import here. If either returns-resolver@1 or the ten returns-baseline sessions is missing, return to the example README and resolve that setup failure before continuing.
Survey before judging
An evaluator is a reusable measurement. An evaluation is one stored result from applying a particular evaluator version to one session.
Run low-cost deterministic evaluators across the population:
These evaluators read stored nodes and make no model calls. They can reveal missing data, failed tools, unusual trajectories, model-call patterns, cost, and timing. They cannot decide whether a refund, replacement, or escalation was correct.
Print a compact inventory:
Select a bounded worklist that you can review carefully. Include different final actions and tool paths, at least one operational outlier, and at least one random session. Summary fields help choose where to look; they are not verdicts.
Inspect complete traces
Set the UUID of one selected session and inspect every node with its payload:
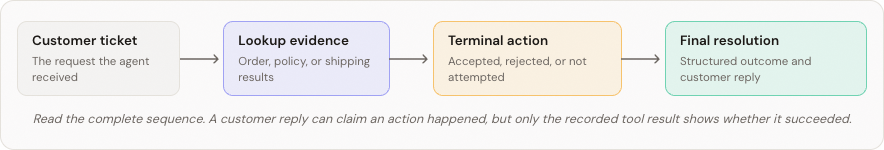
Repeat this command for each selected session. Read the input, model decisions, tool inputs, tool results, and final output together. A final response may claim that an action happened while the tool result proves otherwise; a tool failure may explain behavior that looks irrational in the summary.
Record the session UUIDs and any node UUIDs that contain useful evidence. A node ID is an address for a recorded event, not a judgment about that event.
For each session, write down:
Selection reason
Why this trace belongs in a varied review worklist.
Open question
One concrete point that requires human judgment.
Evidence
Exact nodes or fields that help answer the question without stating the answer.
Keep each question neutral and specific to its trace. "Was this handled correctly?" is too generic. "Given the policy result and accepted action shown here, was escalation required?" identifies the decision without supplying its verdict.
Checkpoint
You now have:
returns-resolver@1, the registered baseline agent version;ten imported sessions tagged
returns-baseline;deterministic survey evaluations;
a bounded, varied worklist chosen from observed evidence; and
complete trace notes with exact session and node UUIDs.
The agent itself has not run and no model call has occurred. Continue to 2. Judge the selected behavior.
Last updated
Was this helpful?